



Blog
10
min read
The Agent With No LLM Inside: What Jev and System One Models Mean for AI Security

10
min read
A System One model is an AI model that returns typed decisions with calibrated probabilities instead of generated text. You give it a block of application state and a fixed set of questions, and it answers every question at once: which option, what score, yes or no, each with a probability attached. It never writes a sentence, so it can never produce a malformed answer, and it runs in a single forward pass rather than token by token. TypeSafe released the first one, Jev, on September 15, 2026. Within 48 hours it was on a mainstream model gateway and inside a working agent that contained no language model at all. This post explains what that class of model is, what it removes from the AI security stack we have spent three years building, what it leaves in place, and why the net effect is more defensible systems, not fewer.
The lamp
Last Thursday a developer told his chatbot to turn off a lamp. Three hundred milliseconds later it was off. There was no LLM anywhere in the loop.
The bot, built by CJ of the developer channel Syntax from TypeSafe's own smart-home demo, asked Jev three questions on every turn. Is this a request, a confirmation or a cancellation? Which of the registered tools would fulfill it? What arguments does that tool need, pointed to as spans in the user's message? The tools were unmodified MCP servers: Home Assistant, Wikipedia, web search, unit conversion. Code made the call. All three answers came back in one response, in roughly 200 ms, with a probability on each.
Nothing in that loop wrote text. Nothing in it reasoned in a way you could read. And nothing in it needed a prompt in the sense we have spent three years learning to defend.
What is a System One model?
TypeSafe's own definition is the one to keep: "a class of AI models built to make fast, structured decisions that software can use directly. A System One model evaluates a state and returns typed answers and probabilities."
The name comes from Daniel Kahneman's Thinking, Fast and Slow: System 1 is fast and intuitive, System 2 is slow and deliberate. TypeSafe argues that a purpose-built System 1 can be more reliable than an LLM asked to behave like one, because the output space is enumerated in advance. You define the answers through three primitives:
Jev, the first System One model, is trained with a method TypeSafe calls Reinforcement Learning for Calibrated Decisions (RLCD). The reward is calibration rather than human preference: higher confidence should mean higher accuracy across a population of answers. Sampling is parallel, every question answered in one pass rather than one token at a time, which is where the speed and the free output tokens come from. The model accepts text only, up to 32k tokens of state in a 64k request, and is currently offered as a hosted API from the US West Coast, with zero data retention available under an enterprise agreement.
The founder, Diogo Almeida, spent his OpenAI years on the instruction-following methods behind ChatGPT. His framing of the gap is blunt: "Models have been superhuman at chat for years, so where is all the automation?" His answer is that strings are the wrong interface for software. They need parsing and validation, they take seconds, their confidence is uncalibrated, and "there is also always some risk that the AI goes off the rails."
How is a decision model different from an LLM, and from a fine-tuned classifier?
Security teams already run small models inline. Pillar's prompt-injection scanner runs on a fine-tuned open model at a few hundred milliseconds P95, and single-purpose classifiers that read a verdict from next-token logits are a well-established pattern for inline checks. It is worth being precise about how a System One model differs from both the LLM-as-judge and the fine-tuned classifier, because the differences are exactly where the security implications live.
The first row is the one that matters. A judge model produces text you must trust your parser to read. A classifier produces one label per model. A System One model produces the entire decision surface of a workflow step, typed, in one call, and the calling code owns what happens next.
Why does an agent with no LLM break the AI security stack?
Look at what AI security has been built to inspect since 2023.
Prompt scanning assumes a prompt going into a language model. Output filtering assumes generated text coming out. Chain-of-thought monitoring, which OpenAI made mandatory for tool-using runs at the frontier this August, assumes a reasoning trace to read. Every one of these controls has an LLM call as its anchor.
The lamp bot has no prompt in that sense, only state and typed questions. It has no generated output to filter. It has no chain of thought, because Jev does not reason in words. Three of the industry's primary detection points are simply absent from the architecture.
What the bot does have is state. And this is where TypeSafe's documentation earns unusual respect. Its published limitations page for jev-1.13 says: "State is data, and jev-1.13 does not treat it as hostile by default. Content written to adversarially steer the model, whether that is an injected instruction, a deliberately misleading framing, or text that argues for its own classification, can move the answer." The suggested mitigation is to write precise criteria and test before deploying widely.
So the Wikipedia page the bot just retrieved, or the web-search result, or the email it is triaging, can vote on which tool fires next and with what arguments. That is indirect prompt injection with the prompt removed. The attack surface did not shrink. It relocated from the instruction channel to the data channel, which is where most of it already lived in agentic systems, and it lost the one thing defenders could previously read.
Does zero hallucination mean zero risk?
No, and TypeSafe is careful about this in a way its headline numbers are not.
The launch post shows a structured-output error rate of 0% for Jev against 0.58% to 45.5% for frontier LLMs, and a tool-call error rate of 0% against figures as high as 16.6% and 17.0% for GPT-6 Astra and Sol. Then it adds: "Our number is not empirical. Schema matching is guaranteed." The model cannot emit an answer outside the declared set. That is a type guarantee. It says nothing about whether the answer inside the set is right.
Put concretely: Jev will never call a tool that does not exist. It can call the wrong tool with perfect type safety.
The same care applies to calibration. TypeSafe's concept page states that "Calibration is measured across groups of predictions; it does not guarantee that an individual answer is correct." Its limitations page goes further with measured examples. The same refund question scored 0.22 as a Noul and 0.01 as a yes/no Choice on the same ticket. A question and its negation, asked as two Nouls, summed to 1.19. The probabilities are honest at the population level and cannot be combined arithmetically across questions. A policy layer that reasons "P(malicious) + P(benign) = 1" will be wrong.
None of this is a criticism of the model. It is the precise boundary of what a calibrated decision model promises, stated by the vendor, and it is the boundary every security control built on such a model inherits.
How does Jev actually perform on a security workflow?
TypeSafe published four evaluation workflows, and the simplest is a security operations task: take one alert with its joined records and decide whether to close it, queue it or act. Its published decision graph reads like a runbook. Triage with three questions: is this unauthorized, does a record explain it, how strong is the evidence. Act if the probability of unauthorized activity exceeds 0.75. Route identity alerts in a 0.15 to 0.60 grey zone to the user rather than an analyst. On an act, run eleven containment readings covering leaked credentials, live attacker sessions, malicious mail, persistence, running processes, egress and blast radius, then take the first matching playbook group.
On that workflow, Jev agrees with the frontier reference 61.7% of the time at $0.0001 and 0.3 seconds per case. Opus 5 scores 66.2% at $0.0574 and 15.1 seconds. GPT-5.6 Sol scores 62.5%, Sonnet 5 60.8%. The reference is the averaged judgment of GPT-6 Astra and Fable 5.1 at high reasoning, not ground truth, so read these as agreement rates.
Two things are true at once. Jev is not the smartest model in the table. And it is roughly 50 times faster and 500 times cheaper than the one that is, on a task that today waits in a SOC queue for a human. That combination, not raw accuracy, is what changes the economics of verification.
What does this do to AI guardrails?
TypeSafe ships a cookbook for exactly this. One request per message carries four Noul hazards (jailbreak, harmful request, medical advice, self-harm) plus a four-level severity Score. Code thresholds them: review at 0.35, act at 0.70 under a strict policy or 0.85 under a permissive one, and a severity of 2.0 upgrades any review to a block. The routes are pass, review, block or support. On its sample, a verbatim DAN jailbreak scored 0.98 and a "Neurosemantical Inversitis" social-engineering jailbreak scored 0.74, which is a block under strict and a human review under permissive, from the same probability.
That last detail is the real contribution. The rule is not in the weights and not in a system prompt. It is a number in the caller's code, and a product decides how much evidence it wants before it acts. TypeSafe's own line is "TypeSafe supplies the assessment; your application owns the decision." Anyone who has watched a guardrail deployment stall on false positives will recognize what a review band and a tunable threshold are worth.
It is also worth being clear about scope. The cookbook covers jailbreak, harm, medical and self-harm on chat text. It does not cover indirect injection through documents or tool results, sensitive data, secrets, restricted topics, or tool calls, and it publishes no false-positive or false-negative rates. It commoditizes the chatbot-moderation floor. It does not address what agents actually do, which is retrieve, call, connect and act.
Where does this leave defenders?
Three years of runtime AI security asked whether the model could be trusted, and looked for the answer in the model's inputs, outputs and reasoning. System One models remove two of those three surfaces and blind the third. They do it while making inference so cheap that the decision layer itself can be rebuilt without a language model.
What they leave untouched is the layer where an agent touches the world. The tool call still has to be made. The query still has to be issued. The connection still has to open. That layer is architecture-agnostic: it looks the same whether the decider is Opus 5, a fine-tuned classifier or POST /v1/systemone. It is also the only layer where a wrong decision becomes an actual event, and the only one an attacker cannot argue with.
Here is what makes this an opening rather than a setback. For the first time, an agent's decision is a number. Not a paragraph you parse and hope. A probability you can log, threshold, audit and replay, produced at a price where checking every action costs less than the action. The rules move out of the prompt and into code a security team can read, test and version. Retrospective audit of every agent transcript, which is how Anthropic found the incidents in its own evaluations this summer, becomes affordable at the scale agents actually run.
The practical agenda follows from that.
- Inventory the new dependency. typesafe-ai/jev, typesafe_sdk, experimental_evaluate and /v1/systemone are now strings that can appear in any repository with a Vercel account. Treat them as AI usage the same way you treat an OpenAI key.
- Move enforcement to the action. Policy that assumes an LLM tool call has to hold when the decider is a classifier. Scope, allowlists and pre-execution checks on the tool boundary do; prompt and output scanning alone do not.
- Red-team the state, not the prompt. Retrieved pages, tool results and inbound documents that argue for their own classification are the injection vector TypeSafe names. Test whether they can change which tool fires.
- Treat every verifier as steerable. A System One judge, an LLM judge and a fine-tuned classifier share the same failure class. Layer them, keep humans on the trust gates, and never let the thing being checked write the check's input unfiltered.
- Adopt the threshold model. Calibrated pass, review and block bands with a tunable evidence bar are a better guardrail UX than a binary label, whatever model produces the score. Expect buyers to ask for them.
- Keep the data path in view. Hosted-only, US-based inference with retention controls gated on an enterprise agreement will not pass every regulated buyer's residency review. That constraint decides where decision models can and cannot sit in a security architecture today.
At Pillar, this is the direction our runtime guardrails and AI red teaming work has been moving for a year: enforce on the action, test the agent through its real interfaces, and treat the model, whatever kind it is, as a component to be verified rather than a witness to be believed. System One models make that posture more necessary and, for the first time, cheap enough to apply to everything.
Next steps
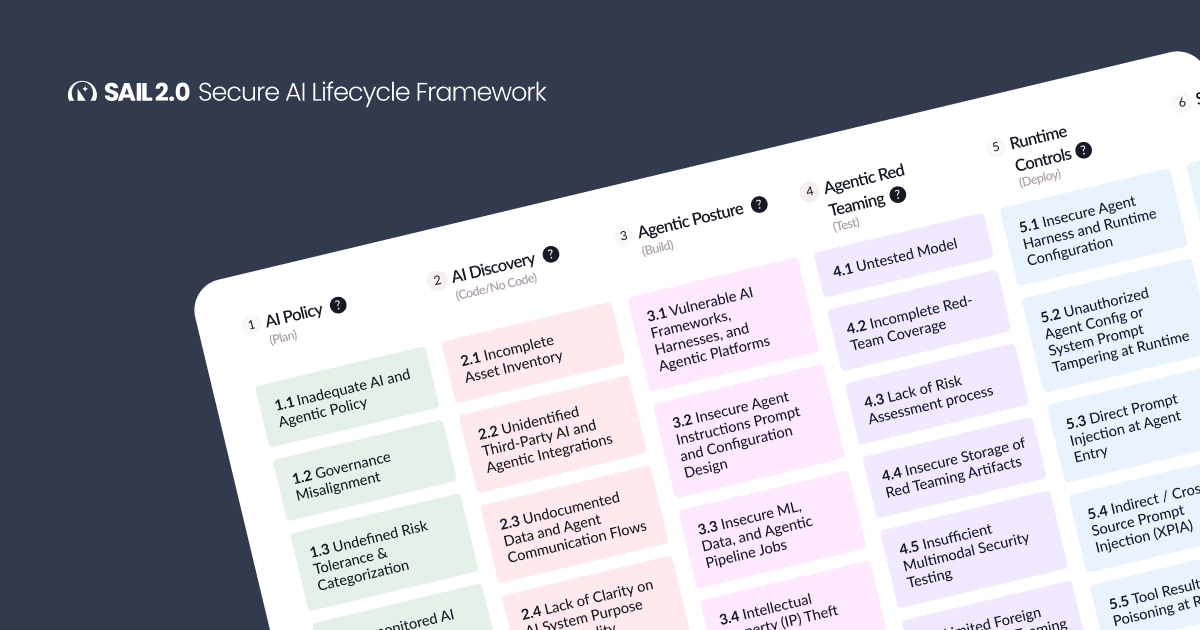
Pillar's runtime guardrails enforce at the action layer regardless of which model is deciding, and our AI red teaming tests agents through the tools and data they actually touch. If you are already running decision models in an agent loop, or evaluating them, we would like to compare notes. The SAIL framework covers where these controls sit across the agent lifecycle.
FAQs
What is a System One model?
A System One model is an AI model that evaluates a block of application state and returns typed decisions with calibrated probabilities instead of generated text. The caller defines the possible answers in advance through Choice, Score and yes/no (Noul) questions, and the model answers all of them in a single pass. TypeSafe coined the term, borrowing Daniel Kahneman's fast, intuitive "System 1" from Thinking, Fast and Slow.
What is Jev?
Jev is TypeSafe's first System One model, released in early access on September 15, 2026. It accepts text state up to 32k tokens, answers up to 255-way Choice questions, responds in roughly 70 to 500 ms, and is priced at $0.042 per million input tokens with free output. It is available directly from TypeSafe and, since September 16, through Vercel's AI Gateway as typesafe-ai/jev.
How is a System One model different from an LLM?
An LLM generates text one token at a time and must be parsed and validated before software can act on its answer. A System One model never generates text; it returns probabilities over answers the caller declared, in parallel, so type errors are impossible and latency is a single forward pass. It cannot write replies, code or explanations of its reasoning.
Can Jev be prompt-injected?
Yes, through its state. TypeSafe's limitations page states that Jev "does not treat [state] as hostile by default" and that "an injected instruction, a deliberately misleading framing, or text that argues for its own classification, can move the answer." There is no separate instruction channel to inject, but retrieved documents and tool results that enter the state can steer the decision.
Does zero hallucination mean Jev is always correct?
No. The 0% figure is a schema guarantee: Jev cannot emit an answer outside the declared set. TypeSafe labels the number "not empirical." The model can still select the wrong option, and its calibration is measured across groups of predictions rather than guaranteeing any individual answer.
Is Jev more accurate than frontier LLMs on security tasks?
Not on TypeSafe's own benchmark. On its security-alert triage workflow, Jev agrees with the frontier reference 61.7% of the time versus 66.2% for Opus 5, at roughly one-fiftieth the latency and one-five-hundredth the cost. Its advantage is speed and price at comparable judgment, not superior judgment.
Can System One models replace LLM guardrails?
They can replace the chatbot-moderation layer: jailbreak, harmful-content and topic checks with tunable thresholds, as TypeSafe's cookbook shows. They do not, by themselves, address indirect injection through documents and tool results, sensitive-data and secrets detection, or tool-call scope, and a System One judge is itself steerable by adversarial state.
What should security teams do about agents that use decision models instead of LLMs?
Inventory the SDK and gateway strings as AI usage, move enforcement to the tool-call boundary where the architecture does not matter, red-team the state that feeds the model rather than the prompt, layer verifiers rather than trusting one, and adopt calibrated pass, review and block thresholds as the guardrail interface.
Subscribe and get the latest security updates

Back to blog